 Mixer AI




How to make an AI avatar video from a photo and your voice
A digital avatar, or talking portrait, is a character made from one photo and a voice recording: the model animates the portrait and moves the lips to the sound. In Mixer AI this kind of avatar comes from Kling AI Avatar, Kling AI Avatar v2 and OmniHuman 2.0, and the clip lasts as long as the audio.
More
Need your look in different scenes in photos and video? That is a separate guide, How to create an AI double: a digital copy of a person in photos and video.
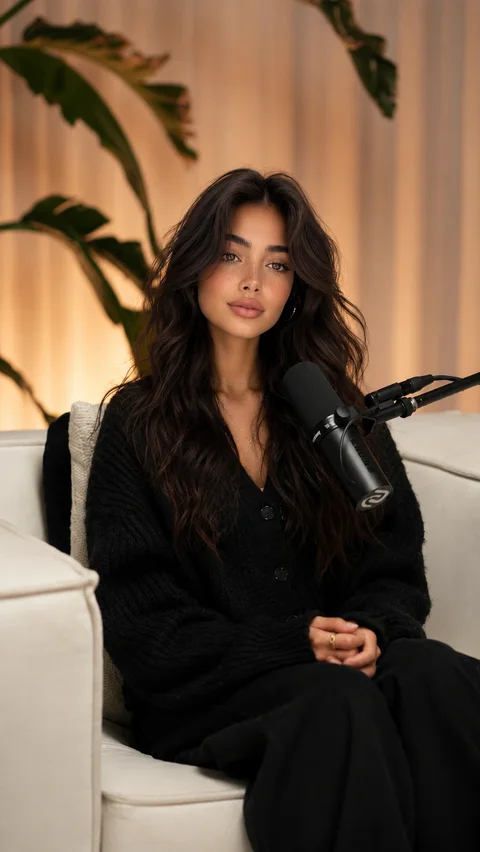
The girl sits on a sofa by a microphone and talks calmly to the camera, tilts her head slightly and gestures with both hands, smiling softly in the pauses. The torso stays almost still. Medium shot, locked camera. The warm soft light, curtain, plant and microphone from the photo stay the same.
Step by step
Prepare the audio: record speech in a quiet room or voice a script on the canvas with ElevenLabs.
Remove background noise, check names, pronunciation and pauses, and trim silence at both ends — clip length and price follow the audio length.
Pick a model: Kling AI Avatar or Kling AI Avatar v2 — Standard to test, Pro for the final; OmniHuman 2.0 when you want body motion to the sound, with MP3 or WAV audio from 4 seconds.
Upload the photo and audio.
Add a short prompt about manner: emotion, gestures, camera position.
Make the first clip on a short line and check the lips, chin and end of the line.
AI avatar prompts
The person speaks to the camera confidently with a slight smile and raises the eyebrows a little on key words. The head stays almost still, shoulders relaxed. Close-up, locked camera.
The character sings, gently sways the head to the beat and closes the eyes on long notes. Medium shot, locked camera, the background from the photo stays the same.
Price in coins
AI avatar video: which model to choose
All three models take one photo and one audio file and make a clip as long as the recording. They differ in audio format and in how the body moves.
| Model | Audio | What matters |
|---|---|---|
| Kling AI Avatar | Up to 5 minutes, up to 100 MB | Speaks and sings; Standard and Pro |
| Kling AI Avatar v2 | Up to 5 minutes; MP3, WAV, AAC, M4A, MP4, OGG | Standard for drafts, Pro for the final; prompt optional |
| OmniHuman 2.0 | MP3 or WAV, 4 seconds to 5 minutes, up to 15 MB | 720p clip, body motion to the sound |
Duration, resolution and aspect ratio are not selectable: the clip follows the audio length and the photo frame.
Creating an AI avatar: which photo works
A sharp frontal portrait with the face filling a good part of the frame and even light works best. A small face, shadows, glasses and a turned head hurt lip sync and likeness.
An illustration with a clearly visible face works too. If you need the same character in many scenes, build a character sheet first — that is covered in the AI double guide.
Voice: how to make a photo talk
The most direct way is to record the speech yourself: no noise, pauses where you need them. Use your own face and voice, or someone else's only with that person's permission.
If you need a narrator, voice the script on the canvas with ElevenLabs: you choose the voice, pace and stability, and a dialogue gets a separate voice for each line. Process each speaker as a separate clip and join them in an edit.
How to animate a portrait without distortion
Singing and loud music are harder on lip movement than speech: for a song, use a track with clear vocals. Several voices in one recording throw off the sync.
If the face drifts in the clip, start with a sharper photo and a calm prompt without sharp head turns. Check the beginning, middle and end of the clip.
Which model to use

FAQ
How do I create an AI avatar?
Upload a frontal portrait and a speech recording to Kling AI Avatar, Kling AI Avatar v2 or OmniHuman 2.0, and optionally add a short prompt about manner. The model makes a clip as long as the audio, up to 5 minutes.
How do I make an AI avatar with my own voice?
Record your speech in a quiet room and upload the file with the photo. Avatar models move the lips to any recording, no separate voice setting is needed.
Can I enter text instead of audio?
Avatar models accept only finished audio. Voice the text on the canvas with ElevenLabs first, then upload the resulting file.
Can a talking avatar from a photo sing?
Yes, upload a track with clear vocals. Several voices and loud accompaniment make lip sync harder.
How do I make a conversation between two talking portraits?
Make a separate clip for each speaker with their photo and their lines, then join the lines in an edit.